Which AI Bots Actually Read Your Site? Your Server Logs Already Know
October 8, 2026
A founder recently told me, “I added robots.txt and llms.txt, so ChatGPT should be able to find my site now.”
That is only half the job.
Those files tell crawlers what they should do. Your server logs show what they actually did.
In ten minutes, you can check whether GPTBot, OAI-SearchBot, PerplexityBot, ClaudeBot, or Googlebot has visited your website, which pages they requested, whether your server let them in, and whether suspicious scrapers are pretending to be legitimate bots.
This matters across three areas:
- SEO: Reduce crawl waste and keep important pages accessible.
- AEO: Make sure retrieval bots can reach the pages you want quoted.
- Security: Find fake bots, hammered endpoints, exposed backups, and leaked paths.
Which bots should you look for?
These are the main user-agent names to search in your access logs.
| Bot | Operator | Main purpose | What a successful visit can tell you |
|---|---|---|---|
| Googlebot | Traditional search crawling, including pages that may support AI search features | Google can access the requested URL | |
| OAI-SearchBot | OpenAI | Finding pages for ChatGPT search results | Your page may be available for ChatGPT search retrieval |
| GPTBot | OpenAI | Crawling content that may support model training and improvement | OpenAI’s training crawler reached the URL |
| PerplexityBot | Perplexity | Finding and retrieving pages for Perplexity answers and citations | Perplexity can potentially cite the page |
| ClaudeBot | Anthropic | General web crawling for Claude-related purposes | Anthropic’s crawler reached the URL |
OpenAI treats OAI-SearchBot and GPTBot separately. Allowing one does not automatically allow the other. OpenAI’s crawler documentation explains the difference.
Also watch for Claude-SearchBot, ChatGPT-User, and other crawler names. User agents can change, so check the official documentation for each service before making permanent rules.
A bot name in a log is not proof that the request came from the real company. Any scraper can send:
User-Agent: Googlebot
That is why you need to inspect the IP address and request behavior too.
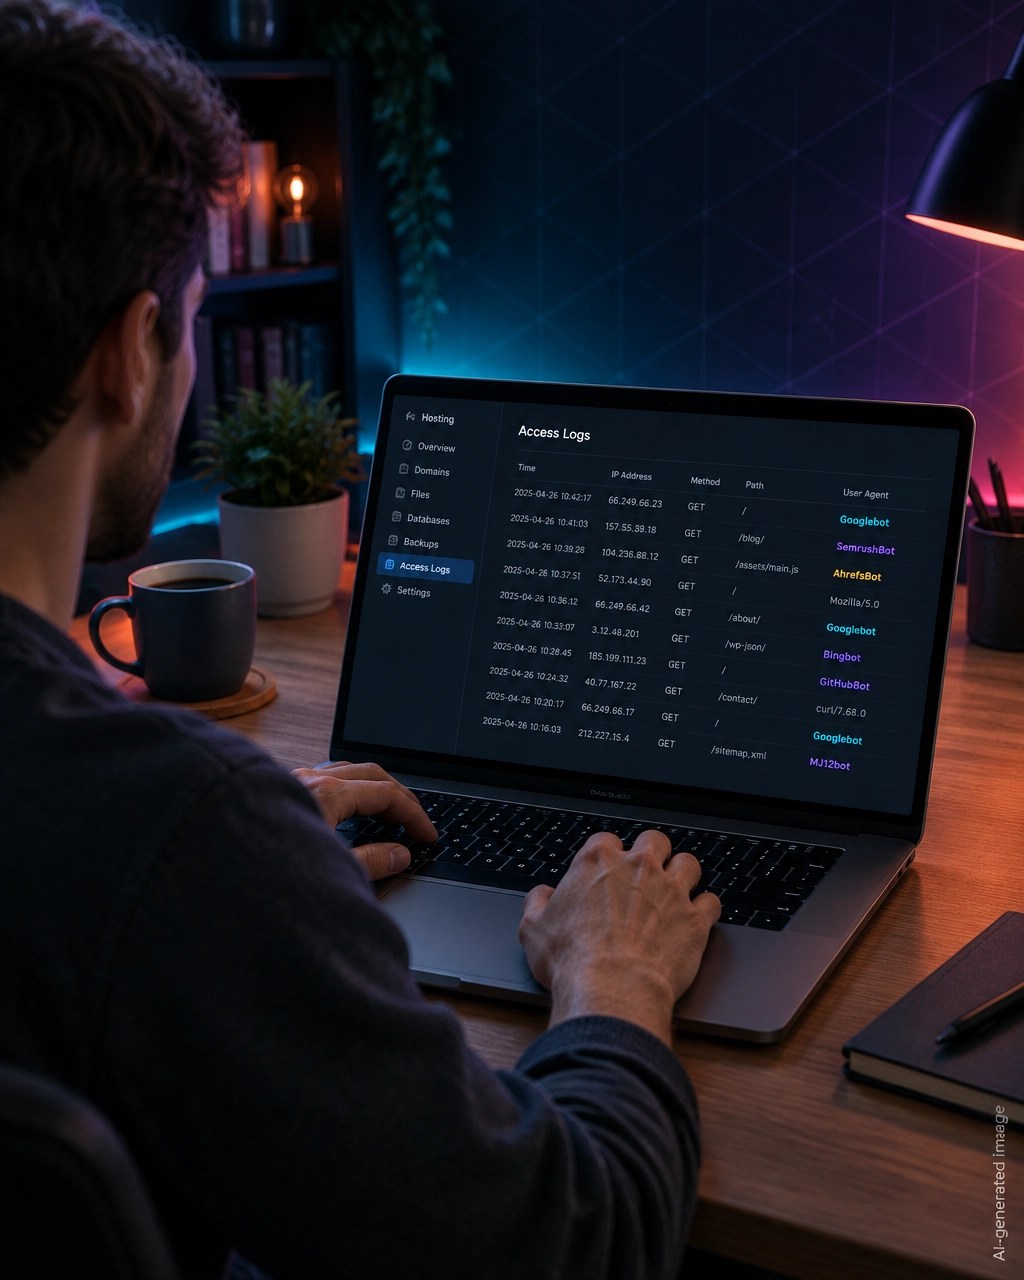
The 10-minute server log check
You do not need command-line experience for this. Most hosting providers expose raw access logs in the hosting panel.
Look for labels such as:
- Raw Access
- Access Logs
- Server Logs
- Request Logs
- Traffic Logs
- Analytics Logs
Cloud hosting dashboards and CDN panels often have an equivalent section. If you cannot find it, search your host’s help center for “access logs.”
1. Open the raw access log
Download the latest log file if the panel gives you that option. Otherwise, use the built-in search or filtering feature.
You are looking for lines containing:
GPTBot
OAI-SearchBot
PerplexityBot
ClaudeBot
Googlebot
Search one bot at a time. Record:
- The date and time
- The requested URL
- The status code
- The IP address
- The user-agent string
- How many requests occurred
2. Check the status code
The status code tells you whether the bot successfully reached the page.
| Status | Meaning | What to do |
|---|---|---|
| 200 | The server delivered the page | The bot reached the URL |
| 301/302 | The URL redirected | Check whether the final page returns 200 |
| 403 | The server refused access | Check firewall, rate limits, or bot rules |
| 404 | The page does not exist | Remove broken links or restore the page |
| 429 | Too many requests | Check rate limiting and crawler behavior |
| 500/502/503 | Server failure | Fix hosting or application errors |
A 200 response confirms that the server delivered something. It does not guarantee that a crawler understood the content.
If your page relies on JavaScript to insert the main text, check the raw HTML too. A bot may receive a technically successful response while seeing almost no useful content.
3. Check the pages being requested
Separate useful pages from low-value or risky paths.
Useful pages may include:
- Homepage
- Product and service pages
- Blog posts
- Documentation
- Pricing pages
- Public comparison pages
- Author or company pages
Low-value paths may include:
- Search results
- Filter combinations
- Tracking URLs
- Duplicate parameters
- Empty tag archives
- Infinite calendar pages
- Internal API endpoints
This is where SEO and AEO overlap. If Googlebot spends most of its requests on duplicate URLs, you have crawl waste. If OAI-SearchBot or PerplexityBot reaches your homepage but never reaches your best explanatory page, your internal linking or access rules may need work.
4. Compare the logs with robots.txt
Open your current robots.txt file and compare its rules with the pages in the logs.
Do not assume the file is working because it exists.
Check:
- Whether the file loads at
yourdomain.com/robots.txt - Whether important pages are accidentally disallowed
- Whether different bots have separate rules
- Whether the sitemap URL is correct
- Whether a broad
Disallow: /rule is still present from development
Google explains that robots.txt manages crawler access and crawl traffic. It is not a security system. A blocked URL can still appear in search if another page links to it. Use authentication, noindex, or removal when something must stay private. See Google’s robots.txt documentation.
5. Check your llms.txt assumptions
An llms.txt file can provide a clean list of important pages for systems that support or use that convention.
It does not prove that a crawler has read your site.
Check whether the pages listed in the file:
- Return status 200
- Contain the information described
- Are linked from your public site
- Are not blocked by
robots.txt - Have clear titles and headings
- Explain your products, services, and organization directly
Keep private paths, admin URLs, backup locations, test pages, and internal notes out of both robots.txt and llms.txt. These files are public. Listing a sensitive path can advertise that it exists.
Use the llms.txt file to highlight useful public content, not to hide confidential content.
How to spot a fake bot
A user-agent name is only a claim.
Compare the IP address with the crawler’s published ranges where available. You can also use reverse DNS to see whether the address belongs to the claimed operator.
Then examine behavior.
Signs of a genuine crawler
- Requests arrive at a steady, reasonable pace
- URLs follow a logical pattern
- The bot respects your crawl rules
- The IP matches the operator’s published information
- It requests HTML pages instead of aggressively probing private files
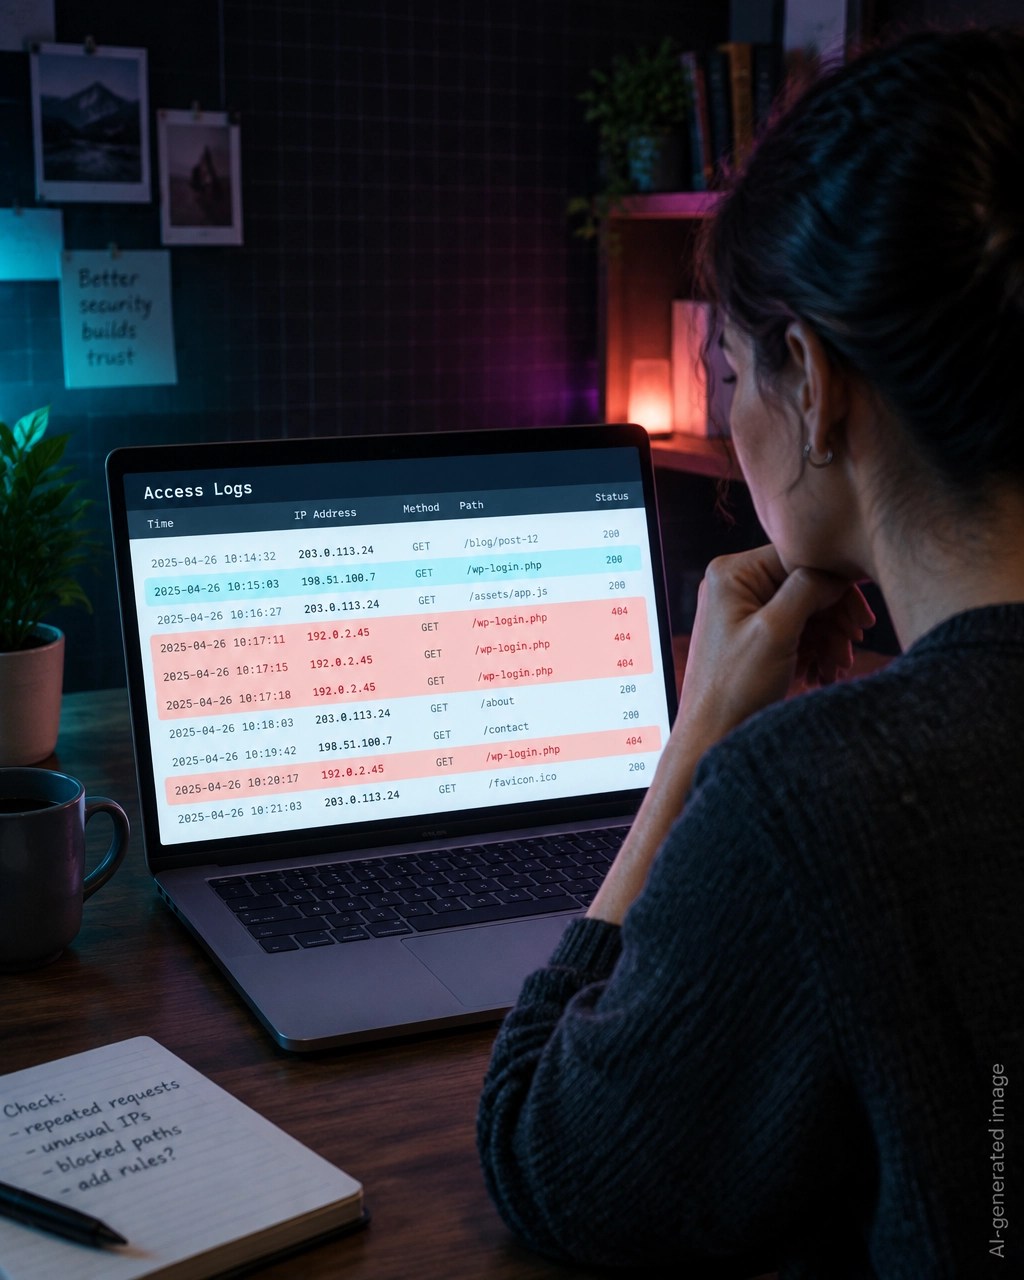
Signs of a fake or abusive crawler
- Hundreds of requests arrive in a short period
- It requests
/wp-admin/, backup files, configuration files, or random extensions - It ignores disallowed paths
- It sends a famous user-agent from an unrelated hosting provider
- It repeatedly causes 429, 403, or 5xx responses
- It changes user-agent names while keeping the same IP and behavior
❌ The setup that looks complete but is not
- Add
robots.txt - Add
llms.txt - Assume ChatGPT and Perplexity can read everything
- Ignore server logs
- Leave admin and backup paths publicly reachable
- Block every crawler when traffic becomes confusing
✅ The setup that works
- Add precise crawler rules
- Check access logs after publishing
- Confirm important pages return 200
- Link your priority pages clearly
- Validate suspicious IPs and request patterns
- Protect private paths with authentication or server rules
- Rate limit abusive traffic without blocking useful crawlers
What to fix after the check
If important bots receive 403 or 429
Review your firewall, CDN, security plugin, or hosting rules. A protection layer may be treating every crawler as a threat.
Allow legitimate crawlers where appropriate, but do not create a permanent allowlist based only on the user-agent string. Verify IPs and keep rate limits in place.
If bots only hit your homepage
Improve internal linking. Add direct links from the homepage to your most important guides, service pages, and explanations.
Use descriptive anchor text. “Read our crawl guide” is more useful than “click here.”
If Googlebot hits duplicate URLs
Reduce crawl waste with canonical URLs, cleaner internal links, and carefully chosen robots.txt rules. Do not block important CSS or JavaScript files if Google needs them to understand the page.
If fake bots hammer your site
Rate limit the abusive IPs, add firewall rules, and protect application endpoints. Do not rely on robots.txt to stop bad actors. Respectful crawlers follow it. Attackers do not.
Check for:
- Exposed
.zip,.sql,.bak, and old deployment files - Public environment files
- Unprotected admin routes
- Test pages
- Debug endpoints
- Directory listings
- Repeated login attempts
A fast-built website can work perfectly while still exposing forgotten files or weak endpoints. That is why crawl monitoring and security checks belong in the same launch routine.
Your practical next step
Run this check after every major website change:
- Open your hosting panel.
- Download or view the latest access log.
- Search for
GPTBot,OAI-SearchBot,PerplexityBot,ClaudeBot, andGooglebot. - Record the URLs, status codes, volume, and IPs.
- Compare the results with
robots.txtandllms.txt. - Fix blocked priority pages.
- Rate limit suspicious traffic.
- Protect exposed admin, backup, and configuration paths.
- Check again after 24 to 48 hours.
You can use the Free Tools page to generate a clean robots.txt file and an llms.txt file.
For a broader check, the free SEO/AEO analyzer reviews crawlability, meta tags, schema markup, internal links, robots.txt, sitemap signals, and answer-readiness. The scan requires no login, no email, and no paywall. You receive the full report every time.
Use the separate Vulnerability Check to look for exposed files, leaked secrets, missing protections, and other security problems. The scan is also free. Sensitive details remain private in the downloadable PDF.
The goal is not to let every bot crawl everything. The goal is to know exactly who is reaching your site, what they can read, what they cannot reach, and what your server is exposing.
That is how SEO, AEO, and security become one practical maintenance habit.
Want to see how your site scores?
Run Free Audit →Get our insights in your Google feed
Follow Smart Analytics and see our latest tips highlighted in Google Search and AI Overviews.